📚 01 · Main Home & Paper Hub
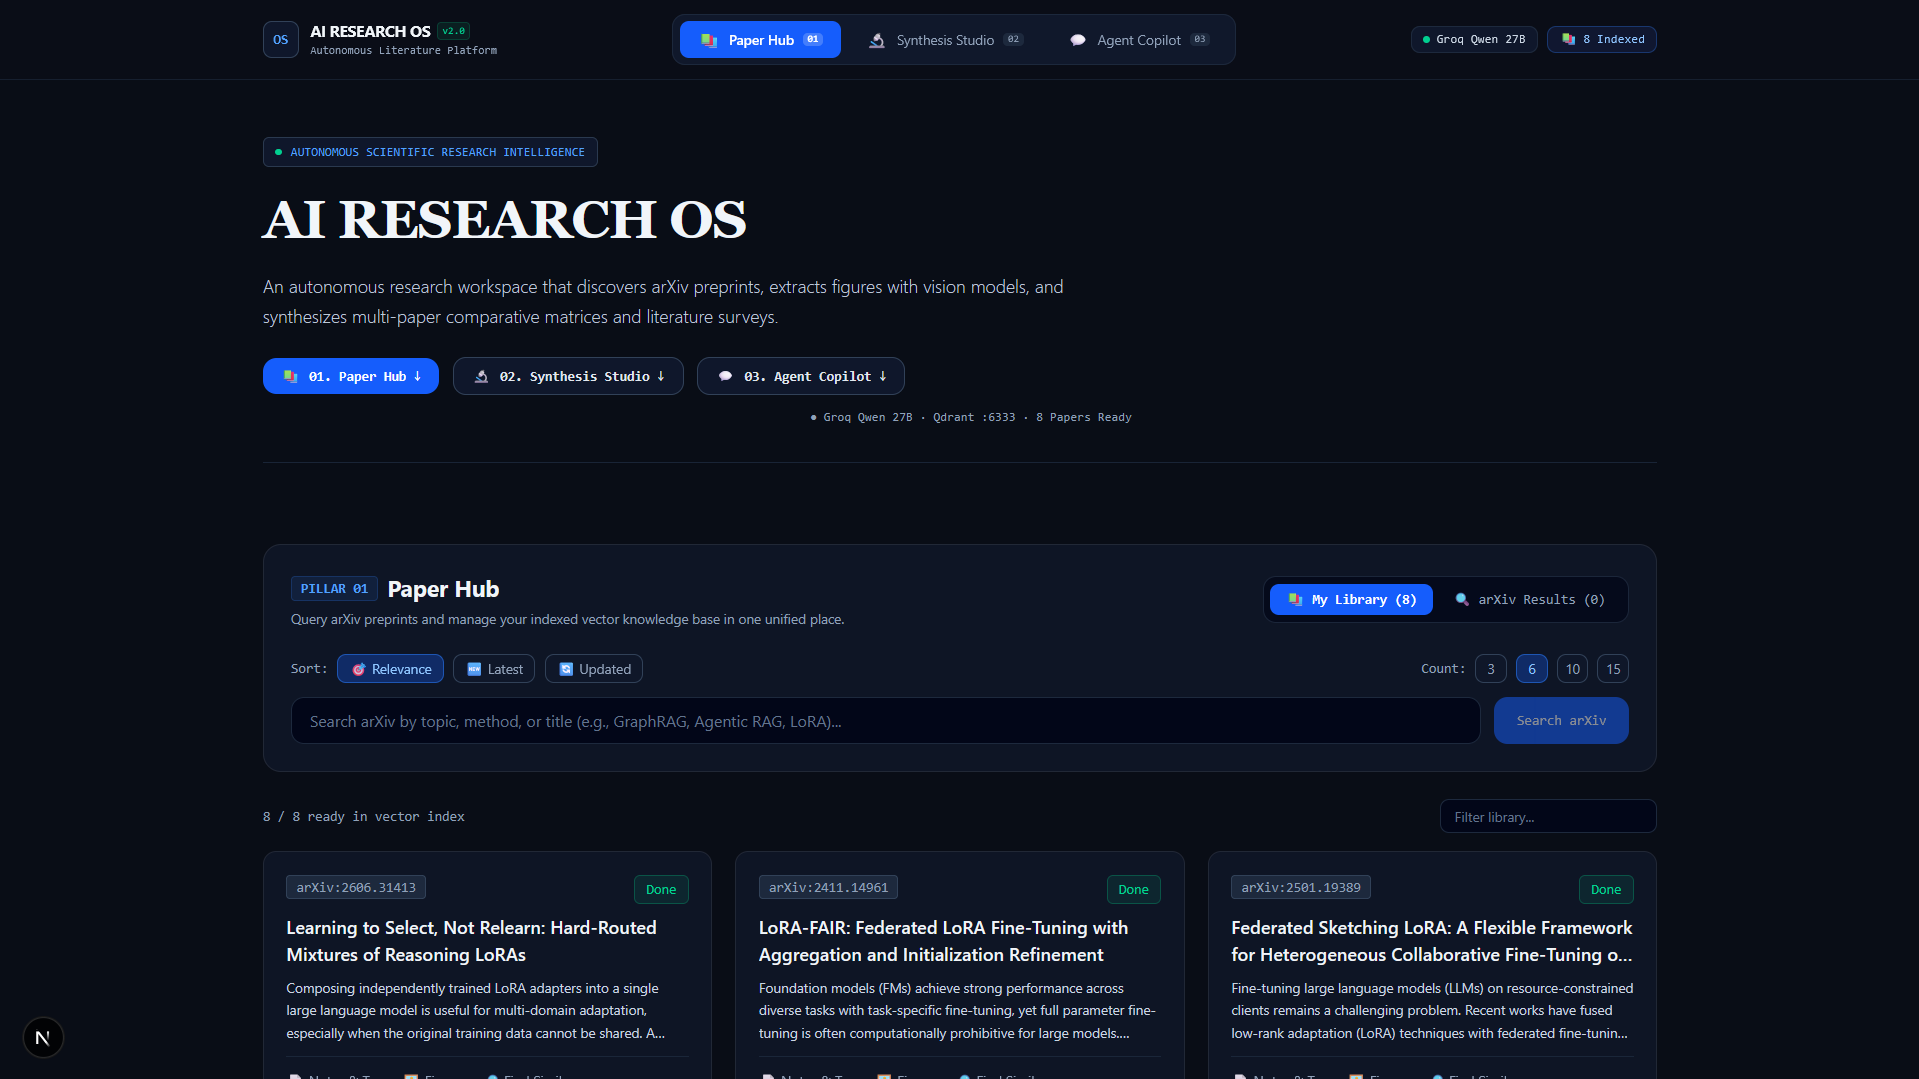
An end-to-end literature research platform built with LangGraph, Next.js 15, and Qdrant. Discovers arXiv preprints, parses multi-column PDFs with Docling, captions diagrams using local vision models, and generates verified literature reviews with paragraph-level clickable citations.
Researchers face an overwhelming influx of new papers weekly. Standard chat models struggle with two-column academic layouts, mishandle mathematical formulas, cannot interpret embedded architecture diagrams, and frequently hallucinate paper citations.
AI Research OS coordinates a specialized 4-agent LangGraph pipeline (Planner, Search, Reading, Writing). It parses arXiv PDFs using Docling layout analysis and Qwen2.5-VL vision models, indexes chunks in a Qdrant vector database, and streams responses with exact paragraph-level citation badges so every claim is verifiable.
Search arXiv with relevance/date filters, batch-queue papers in one click with duplicate prevention, and track real-time parsing pipelines.
Combines fast-path pdfplumber with Docling layout-aware fallback, extracting formulas [MATH], markdown tables [TABLE], and figures.
Extracts architecture diagrams and benchmark plots, generating detailed technical captions using local qwen2.5vl:3b vision models.
Server-Sent Events (SSE) streaming chat with live agent step-logs and clickable paragraph-level citation badges opening exact source context.
Routes interactive tasks to Groq (llama-3.3-70b) for lightning speed and background bulk extraction to local Ollama (qwen2.5:7b) with automatic rate-limit failovers.
Surfaces open research problems by cross-referencing paper limitations, builds side-by-side taxonomy matrices, and exports citations in BibTeX/APA format.
Explore the primary user journeys across the 3 core pillars of AI Research OS: arXiv preprint ingestion, comparative multi-paper synthesis, and interactive multimodal RAG copilot.
Real-time arXiv preprint discovery, relevance/date sorting, batch ingestion queue with duplicate prevention, and indexed Qdrant vector status monitor.
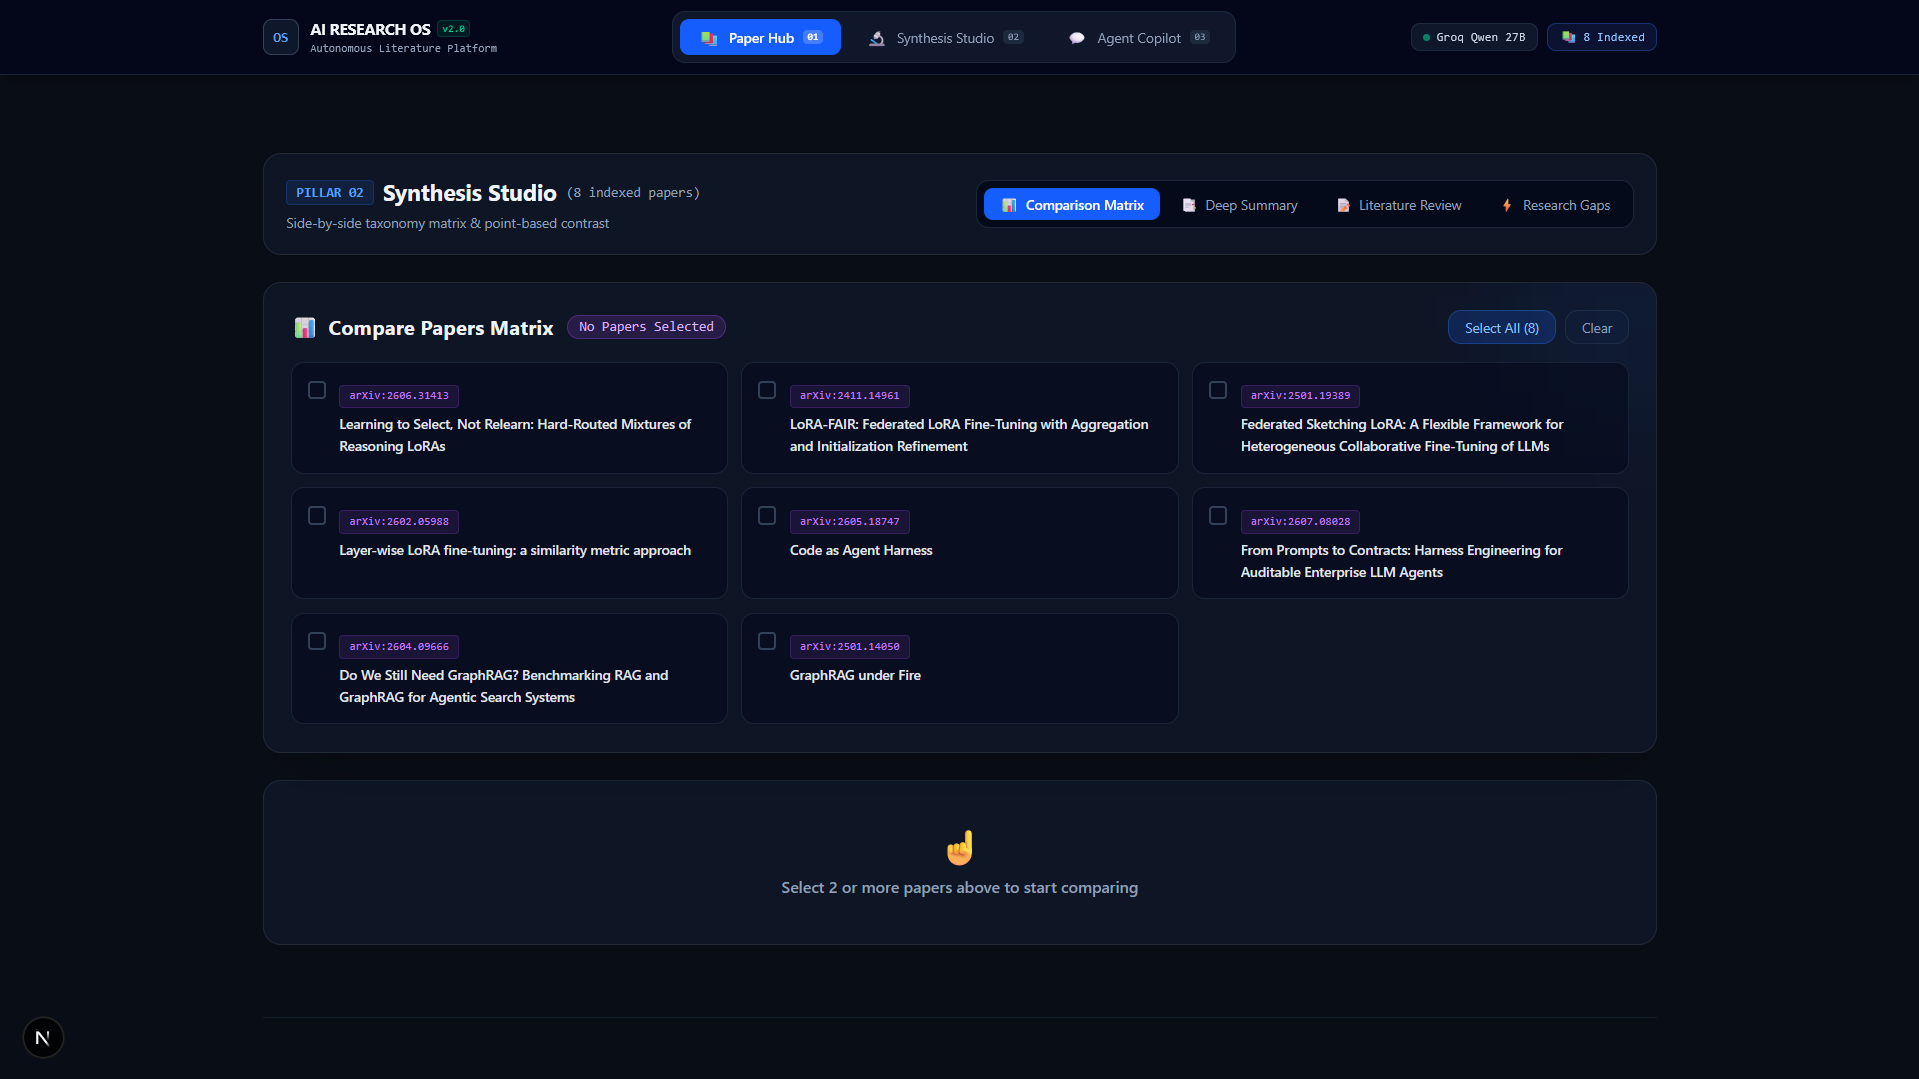
Multi-paper side-by-side taxonomy contrast, comparative evaluation tables, deep literature surveys, and automated open research gap detection.
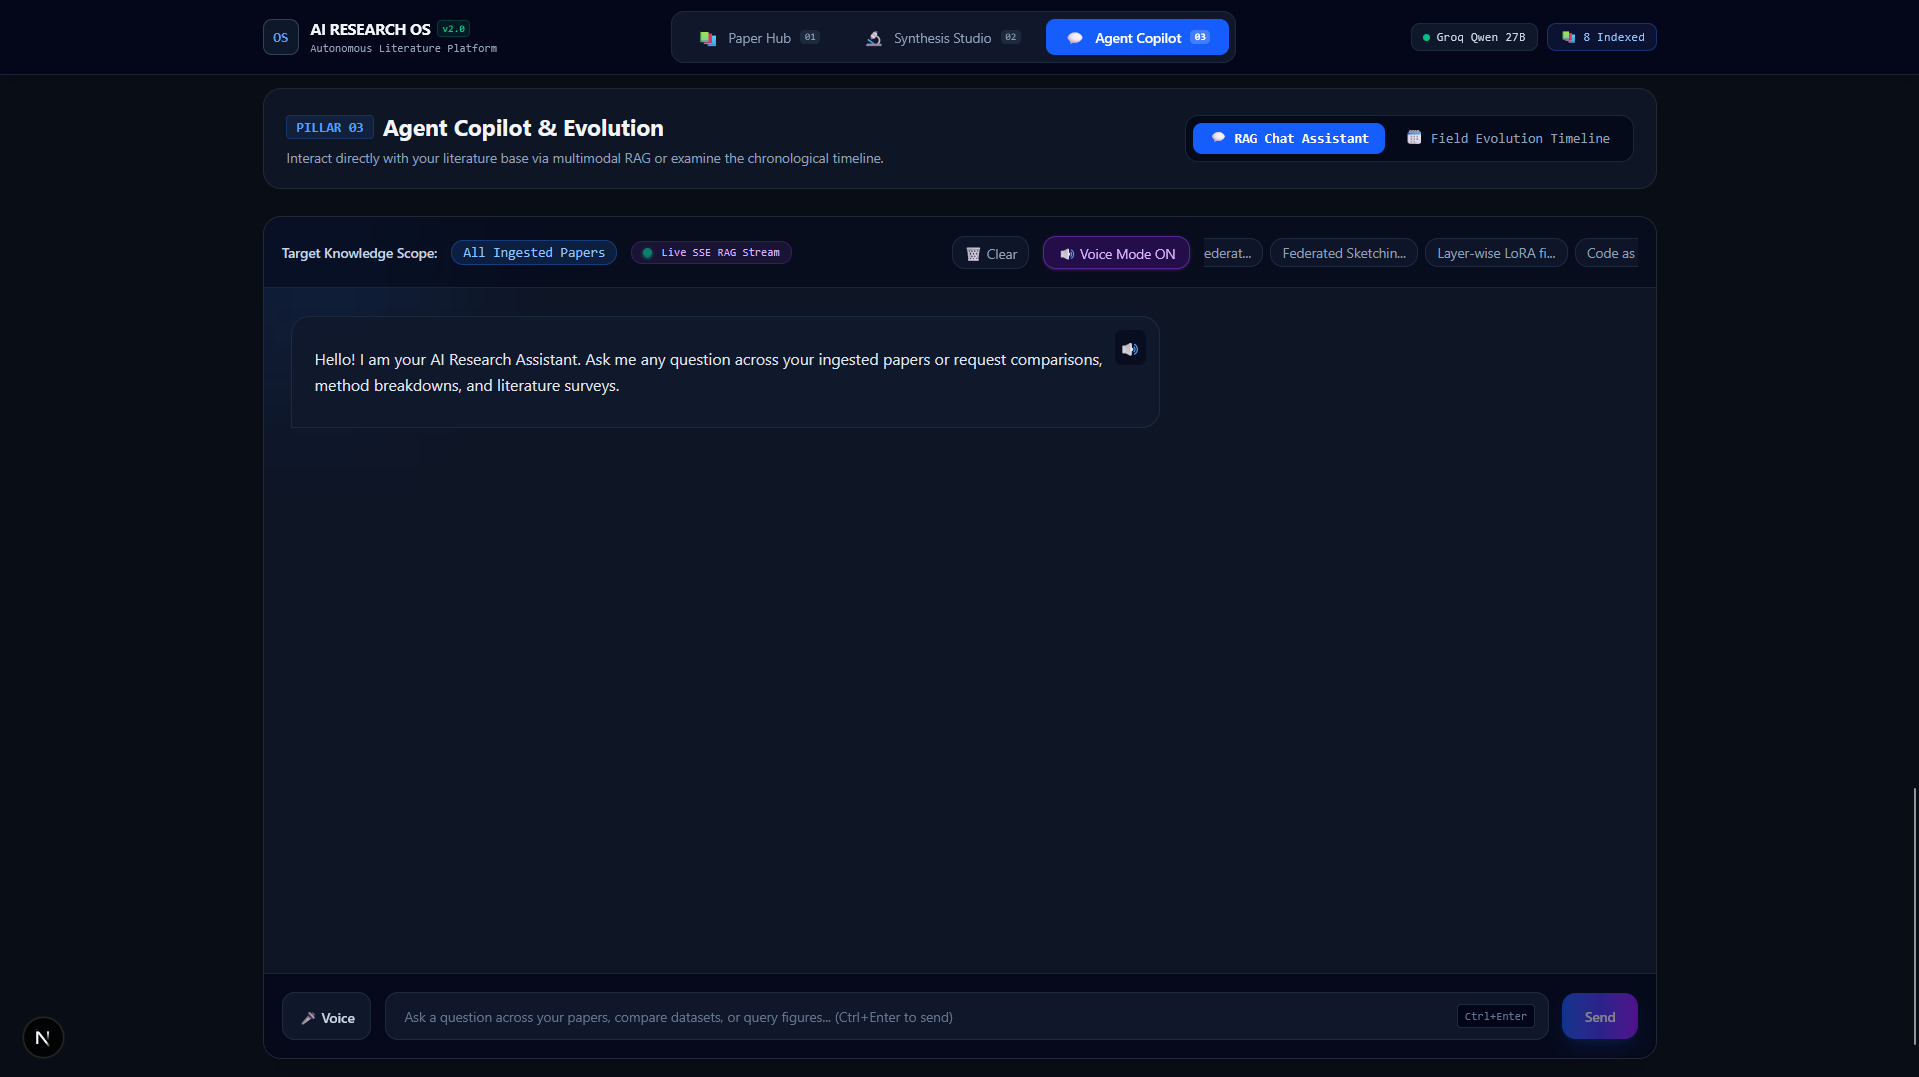
Interactive literature copilot with Server-Sent Events (SSE) streaming, voice research mode, and clickable paragraph-level citation badges opening exact source context.
backend/app/agents/planner.py — Intent classifier routing to QA, comparison, or literature survey pipelinesbackend/app/agents/reading.py — Qdrant vector retriever fetching paragraph-level contextbackend/app/agents/writing.py — Synthesis and citation engine enforcing inline verification badgesbackend/app/agents/gap_finder.py — Cross-references paper limitations to uncover unexplored research directionsbackend/app/services/llm_factory.py — Dynamic dual router connecting Groq 70B and local Ollama instancesfrontend/src/ — Next.js 15 App Router interface with responsive glassmorphic dark theme and audio voice research modebackend/app/services/pdf_parser.py — Layout extraction engine integrating pdfplumber, Docling, and vision captioningbackend/app/services/vector_store.py — Persistent Qdrant vector database with semantic similarity searchbackend/app/main.py — FastAPI server providing SSE streaming endpoints and BibTeX/CSV export APIsModern frontend with SSE real-time streaming, interactive matrix views, and citation drawers.
Stateful cyclic multi-agent graph orchestration paired with high-performance asynchronous REST endpoints.
Ultra-low latency Llama-3.3-70b cloud inference with local Qwen2.5-7B and Qwen2.5-VL-3B vision models.
High-dimensional vector similarity store with layout-aware multimodal PDF document extraction.